Penetration testing an AI-built app: what a real test does, finds and costs
A penetration test is a person paid to break into your app for an agreed number of days, who then writes down how. A scan is a tool working through a list. For a small AI-built app the test is usually scoped at two to three days, priced per scope, and it finds the same handful of things every time.
In this article 6 sections
What a test is, and what a scan is
NCSC defines a penetration test as a method for gaining assurance in the security of an IT system by attempting to breach some or all of that system's security, using the same tools and techniques as an adversary might. The important word is attempting. A tester has a goal, such as reading another customer's data, and a fixed number of days to reach it. They chain small weaknesses together the way an attacker would.
A vulnerability scan is different work. NCSC describes scanning as the automated process of detecting defects, and says that it cannot compare to manual testing for breadth and depth of coverage. A scanner will spot a missing patch or a known-bad header. It will not notice that record 41 belongs to someone other than the person asking for it, because it has no idea what your data means.
NCSC's framing is useful for a founder. It says a penetration test should be viewed as a way of gaining assurance in your own vulnerability management, and that in an ideal world you should know what the testers are going to find before they find it. In plain terms: fix the obvious things first, then pay a person to look for the things you could not see.
The shapes a test can take
The first choice is how much the tester knows. NCSC calls the two ends opaque box, where no information is shared and the tester models an outside attacker, and transparent box, where full information is shared to validate internal controls. The trade calls these black box and white box. In between sits grey box: the tester gets what a real customer would have, usually one or two ordinary user accounts and the public documentation.
For an app with logged-in users, grey box is the sensible default. Most of the damage in a small SaaS happens after login, so a tester without an account spends their first day getting one. Give them two accounts on different plans, plus an admin account if you have one. If you can also give them the repository, the test moves towards white box and the tester covers more in the same days.
The second choice is what gets tested. The four shapes below are quoted separately and often done by different people. Most small apps need the first two, and the third if you run your own servers or a cloud account with more than one service in it.
- Web application: the pages, forms and session handling a user sees in the browser.
- API: the endpoints behind the pages, called directly with a proxy tool, which is where authorisation bugs live.
- Infrastructure: the servers, cloud accounts, storage buckets and open ports around the app.
- Mobile app: the client bundle, what it stores on the phone and the calls it makes home, if you ship one.
Scoping, and why a small app fits in two or three days
Scoping is the meeting where you and the tester agree what is in, what is out and how long it takes. NCSC's guidance lists what the scoping document should contain: the technical boundaries of the test, the types of test expected, the timeframe and amount of effort, usually given in resource days, any compliance requirements, and any specific reporting requirements such as the inclusion of CVSS scores.
Effort follows surface area. A typical AI-built SaaS has one web front end, one API of somewhere between twenty and sixty routes, a hosted database and a handful of third-party services. That is a two to three day grey box job for one tester, with about a day for the report. A marketplace with three user types, file uploads and a payments flow needs longer. Tell the tester the honest size and they will tell you the days.
Bring three things to scoping. A list of every route, including the ones you forgot about, because the OWASP API Top 10 makes improper inventory management a category of its own. Two test accounts with no relationship to each other. And a staging environment with realistic but fake data, so the tester can be aggressive without a customer noticing. If you only have production, say so, and agree in writing what the tester will and will not do to it.
What the tester finds in an AI-built app
The findings in AI-built apps repeat. Most of them sit in four categories of the OWASP Top 10, whose 2025 edition was built from data covering over 2.8 million applications. Broken access control is A01, security misconfiguration is A02, software supply chain failures is A03 and authentication failures is A07. A tester goes looking for each of these on day one, and this is what they usually find.
None of these need a clever payload, which is why they survive: the exploit looks like a customer loading a page, and the tests were written from the happy path where the data is always your own. It is also why a scan misses most of them and a person with two accounts finds them in an afternoon. In rough order of how often they turn up:
- Missing authorisation checks. The route confirms you are logged in and never asks whether the record is yours. OWASP lists this under A01 as insecure direct object reference; the API Top 10 calls it broken object level authorisation and puts it first. The studio wrote up how it looks and how to audit for it in the authorisation bug AI coding tools write by default.
- Secrets in the client bundle or the repository. An API key inlined to make a feature work, shipped to every browser, and still present in git history after the line was deleted.
- Database rules left open. Supabase's own documentation says a table in an exposed schema without row level security is readable and writable by any role with a grant on it. Firebase says its security rules are the only safeguard blocking access for malicious users, and that test mode rules must be replaced before production. Assistants leave both off so that the demo works.
- No rate limiting on login and password reset. OWASP puts brute force and credential stuffing that is not quickly blocked under A07, and recommends limiting or increasingly delaying failed attempts.
- Verbose errors. A02 names error handling that reveals stack traces or other overly informative messages, which hands the tester component versions to look up.
- Outdated dependencies. A03 covers software that is vulnerable, unsupported or out of date, including the runtime and libraries. Generated lockfiles are rarely touched after the first week.
What a good report contains, and the retest
Ask to see a sample report before you sign. A usable finding has four parts. A severity, usually a CVSS score mapped to a word: under CVSS v4.0, 4.0 to 6.9 is medium, 7.0 to 8.9 is high and 9.0 to 10.0 is critical. Exact reproduction steps, with the request and the response, so your developer or your coding assistant can replay it. A recommended fix. And a summary a non-technical reader can act on.
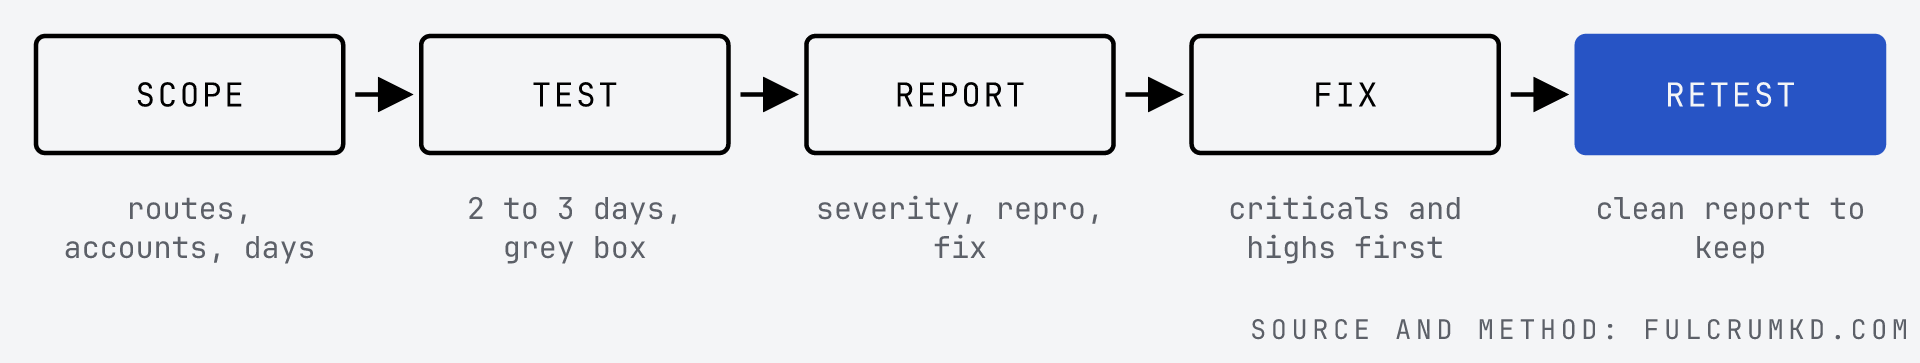
The report is the start of the work. NCSC is clear that risk assessment and decisions on the application of fixes are your responsibility, and that the solutions proposed by your testers may not be the only ones possible. Fix criticals and highs first, then ask for a retest of exactly those findings. Agree the retest window at scoping, so the closed findings end up in a clean report you can hand to a customer or an auditor.
One more thing to check in the sample: does the report say what was tested, what was out of scope and which accounts were used? A clean report on the wrong scope is worth nothing to the person reading it later, and an auditor reads the scope section first.
The test cycle for a small app
Who to use, and what it costs
In the UK the accreditation to look for is CREST. A CREST member company has had its organisational standards, covering quality control and information security practices, and its penetration testing discipline independently reviewed, signs an enforceable code of conduct and is subject to a complaints process. The CREST marketplace lists members by service. For government work NCSC recommends CHECK scheme testers, which is a separate scheme and more than a small SaaS needs.
Read what accreditation does and does not cover. CREST's own accreditation standards page says there is no mandatory requirement for individuals to be CREST qualified for a company to achieve accreditation; individuals are assessed on skills and experience or the qualifications they hold. So ask who will actually do your test and what they hold. On an application test the individual certificates to look for are CREST Registered Penetration Tester (CRT) and CREST Certified Tester, Application (CCT APP).
On price, published figures are thin because quotes are per scope. Cyphere, a UK tester, published day rates of £750 to £1,100 for manual assessments and £1,200 to £1,500 for senior consultants on its site in September 2026, with web application tests starting at £2,500 for limited scope. Other UK providers, GRC Solutions among them, publish no prices and give a fixed quote after a short scoping call. Budget on days multiplied by a day rate, plus the retest, and get two quotes against the same scope document.
The order matters. Fix what the free Code Health Check finds first, because paying a tester by the day to rediscover an open database rule is poor value. Then buy the test. Then fix and retest. That sequence is the security strand of the layer around your AI-built app, and the clean retest report is the document an auditor asks for, covered in SOC 2 for an AI-built app.
Common questions
- Is a vulnerability scan enough for a small app?
- It is a good start and a poor finish. NCSC recommends regular scanning for the low-hanging fruit so that a human test can focus on the complicated issues. The findings that matter most in AI-built apps, missing ownership checks above all, need a person with two accounts and an understanding of what your data means.
- Can the tester work on production?
- Yes, with limits agreed in writing. A tester on production will avoid destructive actions, throttle their own requests and use the accounts you gave them. A staging copy with fake data lets them go harder and find more. If you only have production, back it up first and tell the tester the hours you would rather they avoided.
- How often should an AI-built app be tested?
- NCSC's guidance sets no fixed interval. A practical rule for a small team: test before the first customer who asks for a report, retest after the fixes, and test again after any change to authentication, payments, file handling or the data model. Between tests, keep scanning and keep dependencies current.
- Will the tester need my source code?
- Not for a grey box test, which is the usual choice. Giving them the repository moves the test towards white box and usually finds more in the same days, because a tester can read a route handler faster than they can probe it. OWASP's ASVS notes that some of its requirements cannot be verified without documentation or code.
Written with AI assistance and edited by a human before publication.
// read next
- You shipped an app with AI and people use it. Here is the layer around it
Your AI-built app has real users. The six things that now sit around it: a penetration test, SOC 2, terms, a true privacy policy, GDPR by country, the basics.
- SOC 2 for an app you built with AI, what it costs and who asks for it
What SOC 2 is, Type 1 against Type 2 and the observation window, who actually asks for the report, published audit costs, and what AI-built apps lack.
- The authorisation bug AI coding tools write by default
AI assistants reliably write routes that check who you are but never check what you are allowed to see. How the bug looks, why tests miss it, and how to audit for it.